- Language
- Python
- Last commit
- 3h ago
- Forks
- 5
- Open issues
- 3
- Registry update
- Oct 14, 2026
Connect
pypi$claude mcp add frankensurf \ -- uvx frankensurf==0.43.0
Environment variables
Nothing to configure — it works as is.
Security review
Review passedReviewed 2h ago.
- metadata
- scanned
- packages
- 1 checked
No findings.
Tools
This server runs on your machine, so its tool list is not fetched before install — the README below describes what it offers.

Frankensurf
One read() call for AI agents, stitched from 28 web tools.
Cheapest tool first, every page checked, a receipt for every attempt.



Website · Docs · Quick start · Benchmark · Why I built it
Every web tool breaks somewhere, and they break on different sites. Frankensurf sits in front of all of them and gives your agent one call. It tries the cheapest tool first, checks the page is real, moves to a stronger tool only when a site pushes back, and returns clean page data with a receipt of how it got there.
| Cheapest first Plain HTTP, Jina Reader, a local browser, free stealth browsers, hosted browsers, then paid APIs only if you allow them. | Every page checked A challenge page, a login wall or a search page whose results never loaded counts as a failure, not a success. | Shows its work Every result says which tools ran, how long each took, what it cost, and why it stopped. |
Quick start
Python 3.12+, on Linux, macOS, or Windows through WSL. No account or key needed.
pip install "frankensurf[mcp]"
frankensurf install        # every free tool: browsers, stealth browsers, local search, Crawl4AI
frankensurf read "https://www.walmart.com/search?q=air+fryer" --explain
The read climbs until it gets the real page:
https://www.walmart.com/search?q=air+fryer
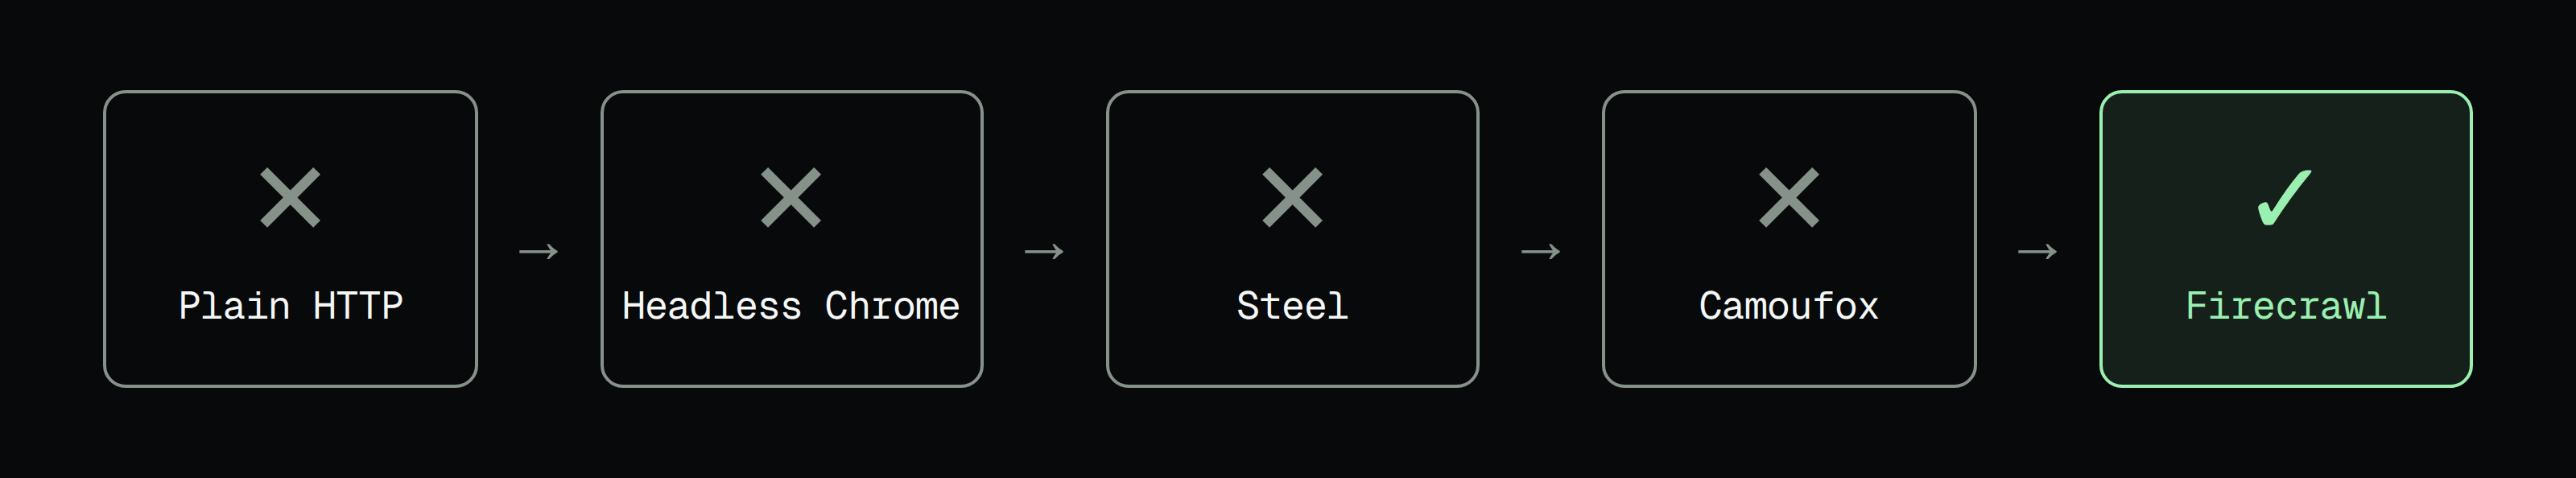
  ✗ http                   CAPTCHA                0.4s
  ✗ local                  CAPTCHA                1.5s
  ✓ camoufox               got the page           15.6s

air fryer - Walmart.com
24,192 characters via camoufox, complete (107 results), free
frankensurf install works like playwright install: name just the tools you want
(frankensurf install search chromium), add --with-deps for the browsers' system libraries on
Linux, --list to see what's installed where, and frankensurf uninstall all to remove it. No
Docker needed. Each release is installed from PyPI on fresh Ubuntu and macOS machines and checked.
Use it
From an agent, as an MCP server (setup for each client):
claude mcp add frankensurf -- frankensurf-mcp
From Python:
from frankensurf import Runtime

async with Runtime("state") as web:
    page = await web.read("https://example.com", policy_overrides={"prefer_markdown": True})
    hits = await web.search("playwright python tutorial")
From the command line:
frankensurf read https://example.com --markdown
frankensurf search playwright python tutorial --recency week
frankensurf watch https://news.ycombinator.com/ --link-pattern 'item\?id=\d+'
In Claude Code as a plugin (the MCP server plus the skill that teaches Claude to use it):
/plugin marketplace add yail259/frankensurf
/plugin install frankensurf@frankensurf
From LangChain, the OpenAI Agents SDK or CrewAI (pip install "frankensurf[langchain]", and so on):
from frankensurf.agent_tools import langchain_tools   # or openai_agents_tools, crewai_tools
tools = langchain_tools()                              # frankensurf_read, frankensurf_search
You get raw page data, not answers: text or markdown, JSON-LD, the page's own JSON, images, and
the receipt. Your agent decides what the page means. If it isn't what it wanted, it asks again with
retry_of=<trace_id> and Frankensurf skips every tool it already tried.
Benchmark
scripts/toolbench.py runs each tool on its own, then Frankensurf, on the same pages with the same
content checks. The newest set: 150 sites in 15 categories, picked before any was read, read once
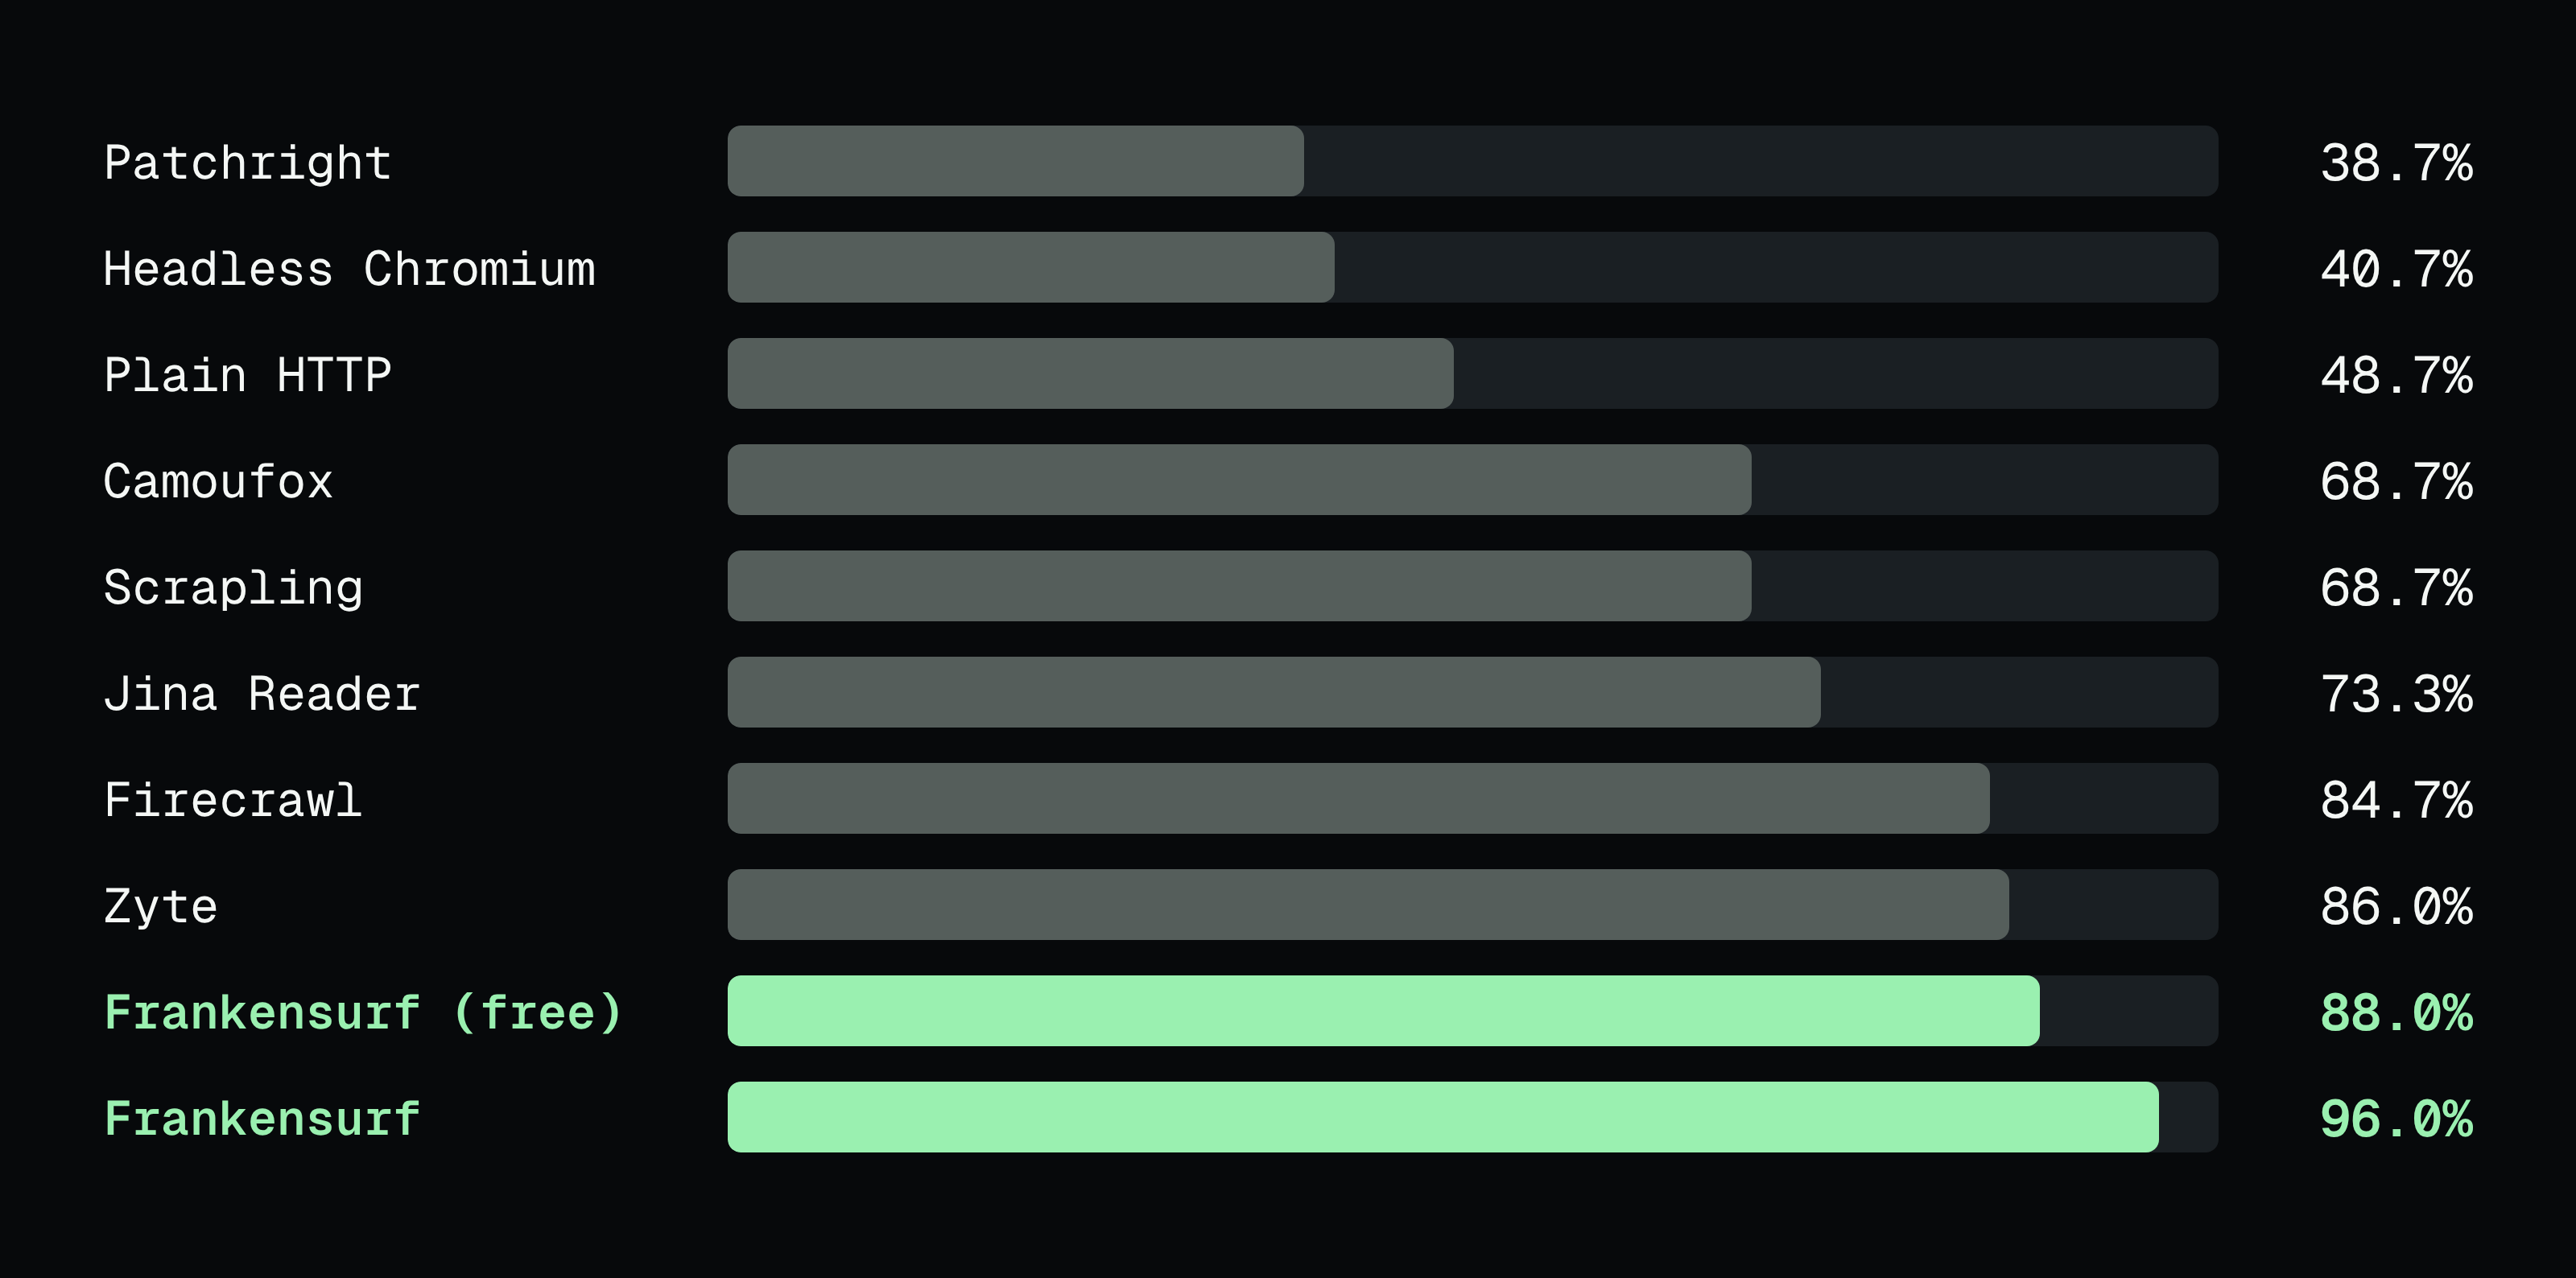
(11 October 2026, raw rows in benchmarks/2026-10-11/).
| Tool | Sites read | Median | Cost per 1k |
|---|---|---|---|
| Plain HTTP only | 48.7% | 1.2 s | free |
| Camoufox only | 68.7% | 10.9 s | free |
| Jina Reader only | 73.3% | 1.5 s | free |
| Firecrawl only | 84.7% | 4.6 s | $4.28 |
| Zyte only | 86.0% | 10.7 s | not reported |
| Frankensurf, free tools only | 88.0% | 3.6 s | $0 |
| Frankensurf, with paid fallbacks | 96.0% | 2.9 s | $0.98 |
- Frankensurf read 17 sites Firecrawl missed; Firecrawl read none it missed.
- With no paid tools at all it is level with the best paid tool on its own (88.0% against 86.0% and 84.7%; at 150 sites that gap is within the noise).
- Its slowest reads are slower: the slowest tenth takes 25.7 s against Firecrawl's 10.6 s, when a read climbs several tools.
- Not a one-off: 95.3% vs 85.3% on the set the day before; 89.5% vs 80.3% and 88.5% vs 74.1% on earlier fresh sets.
Every tool on the same 150 sites
| Tool | Sites read | Median | Cost per 1k |
|---|---|---|---|
| Patchright only | 38.7% | 4.1 s | free |
| Headless Chromium only | 40.7% | 2.7 s | free |
| Plain HTTP only | 48.7% | 1.2 s | free |
| Camoufox only | 68.7% | 10.9 s | free |
| Scrapling only | 68.7% | 8.5 s | free |
| Jina Reader only | 73.3% | 1.5 s | free |
| Firecrawl only | 84.7% | 4.6 s | $4.28 |
| Zyte only | 86.0% | 10.7 s | not reported |
| Frankensurf, free tools only | 88.0% | 3.6 s | $0 |
| Frankensurf, with paid fallbacks | 96.0% | 2.9 s | $0.98 |
Medians are over pages read; cost is per 1,000 pages read right. ZenRows and Scrapfly are left out (their plans ran out of credits). From a fresh cloud VM, whose data-centre address sites wall more often: free tools 82.0%, lightning mode 84.0% at a 1.2 s median. See Benchmarks.
Search
search uses free sources first and checks every result: on topic, the right kind of page, inside
the date window. Exa, Brave, Tavily, Serper and other paid sources join only when you allow paid
tools. Judged blind (results pooled and shuffled, which tool found them hidden), useful results in
the top five:
| Blind set 7 (120 queries) | Useful results (of 5) | Cost per 1k |
|---|---|---|
| Frankensurf, paid allowed | 4.67 | $9.38 |
| Exa only | 4.66 | $9.50 |
| Frankensurf, free (with the local search engine) | 3.83 | $0 |
Free, it beats Firecrawl's search: better on 35 queries, worse on 5. With paid allowed it is level
with Exa. The local search engine (frankensurf install search, SearXNG without Docker) makes the
free tier much stronger. v0.41 improved free search again: on a fresh blind set of 120
queries it beat v0.40 on 41 and lost on 12 (3.42 against 2.71 useful results of 5,
benchmarks/2026-10-14-search-v041/). Details in
benchmarks/2026-10-13-search/.
What else is in the box
Reading: quality grades, main content, racing slow reads, PDFs
- Every read carries
receipt.quality:good,partialorpoor, with flags such aspaywall,menusorplaceholder, so an agent knows when a page didn't really come through. --schema product.json(MCPschema) fills a JSON Schema from the page's JSON-LD, microdata, meta tags and own JSON intoextracted, and climbs to a stronger tool while a required field is missing (Structured fields).--main(MCPmain_content=True) addsmain_text: the article without menus, footers and banners (best withpip install "frankensurf[main]").- A read with no page after 3 seconds starts two more free tools beside it and keeps the first
complete page (
--lightningraces from the start). - A URL that answers "not found" is looked up with the site's own search;
receipt.rescuedsays so. - Still walled? Allow a real Chrome on your machine (
--real-browser, with its own profile, never yours) or a second connection (FRANKENSURF_EGRESS).
Search: verticals, boolean queries, local engine
--site,--exclude-domain,--recencyand--regionon every source, and a--vertical(news, reference, discussions, qa, code, papers, books) backed by official free APIs.- Monitoring-style queries (
"Acme" OR "Acme Corp" (acquisition OR layoffs)) are judged by the name they're about, and a weak answer is retried once with just the name. --mode mergeasks every source at once and fuses the results.frankensurf search-engine start|stop|statusmanages the local SearXNG; search restarts it after a reboot.
Agents: skill, profiles, handoff, site modules
- A bundled skill teaches agents the tools: the MCP server sends it as its instructions, and
frankensurf skill installadds it to~/.claude/skills. - Profiles: log in once and any tool can use the session; the model never sees cookies or keys.
- Human handoff: for a CAPTCHA or 2FA only a person can clear, it opens the page for you, then carries on.
- Site modules: save what your agent learns about a site as data.
frankensurf module discover URL --query "desk lamp" --savefinds the site's search, reads the results and saves a module; after that, searches on that site come back as structureditems. - Shared site knowledge:
frankensurf share syncstarts from which tool reads which site, as the community learned it;share exportwrites yours to review and contribute (opt in both ways). frankensurf watch-sites URL… --since DATElists new pages from the feeds and sitemaps sites publish.
Paid tools and budgets
Everything works with no keys. Paid tools are opt-in and only come in once a site has walled a free
tool, cheapest likely success first. Set their keys (for example FIRECRAWL_API_KEY) and pass
--paid; --max-cost USD caps a read. From Python: allow_paid_fallbacks and max_cost_usd.
See Paid tools and budgets.
How it works
Every way to fetch a page is a rung: plain HTTP and markdown negotiation, browsers, stealth browsers and signed requests, hosted browsers, paid APIs, and finally a person clearing the wall in a visible browser. A read starts at the cheapest rung and climbs only when a page pushes back. Every tool is a plugin, so new ones slot in as another rung.
See How escalation works and the full list of integrations.
Known walls
It's an alpha, and some sites still win:
- Need the paid tools: in a free-only spot check, Etsy, Home Depot, Yelp, Crunchbase and G2 blocked every free tool.
- Beat everything so far: Shopee, Temu and Idealista.
- Social sites without a login: LinkedIn, X, YouTube, Threads, Bluesky and Reddit read fine. Instagram, TikTok, Facebook and Pinterest show only the public shell; the posts need a login.
- Logged-in pages (your feeds, your orders) need a profile.
- A slow tail: most reads take a few seconds, but one in ten climbs several tools and takes 25 s or more.
Found a site it can't read? Report it; every report becomes a test case.
Develop
python3 -m venv .venv
.venv/bin/pip install -e '.[test,mcp]'
.venv/bin/frankensurf install
PYTHONPATH=.:src .venv/bin/pytest -q
The product design is in SPEC.rst and contributor rules in AGENTS.md. New tools are plugins,
never branches in Core: see Writing a plugin and the
example in examples/frankensurf-plugin-example. The website and docs live in site/.
Licence
Apache-2.0. See LICENSE.
From the server's repository — third-party content, read it before running anything it suggests.
More in Browser
scrapeunblocker-mcp
com.scrapeunblocker
Fetch any web page's HTML or AI-parsed JSON, or run 100+ site plugins, via ScrapeUnblocker.
Endform
dev.endform
Find failing, flaky, and slow Playwright tests on Endform and keep your suite healthy as it grows.
mcp-server
io.github.Decodo
Enable your AI agents to scrape and parse web content dynamically, including geo-restricted sites
Agent360 Browser MCP
io.github.Agent360dk
Drive your real, logged-in Chrome from any AI agent - 40 tools. Needs our Chrome extension too.
A11yScope
io.github.perceivable
WCAG 2.2 AA accessibility checks for pages and HTML, run locally in headless Chrome.
chrome-bridge
io.github.frsorrentino
Borrow a tab from your own logged-in Chrome, hand it back; 2FA and CAPTCHA stay yours. 66 tools.
Listing from the official MCP Registry · repository facts from GitHub, 2h ago.